


Open model beats Jev on clinical decisions
pplx-decider v1.1 scored 643/669 on clinical decision tests, outperforming Jev's 628, with 42% lower cost per decision and similar speed. Weights are downloadable for on-premise hospital deployment.

THE JEV GUIDE · CURATED EDITION
Launch news, explanations, demos, and community projects around TypeSafe Jev, organized by topic. Every entry links back to its X source.
Curated selection · Not exhaustive · Updated manually
Sponsors
These products pay for the directory. Want yours up here?
pplx-decider v1.1 scored 643/669 on clinical decision tests, outperforming Jev's 628, with 42% lower cost per decision and similar speed. Weights are downloadable for on-premise hospital deployment.
Mr Vu shares a sneak peek of a cross-country medicine search powered by JEV for search planning and EmbeddingGemma 2 for embeddings.

This post shares cost and speed data for Jev and other models on clinical decision tasks, comparing total cost across 9 APIs and noting the fastest 3GB local model responds in 284 ms.

In the demo, 20 patients wait with 3 doctors and 3 rooms. When a room frees up, Jev (TypeSafe Choice) picks the next patient based on sickest ESI level first, with ties broken by earlier arrival.

A radiology resident built JevRad (educational use only) using TypeSafe's Jev model. After describing a patient, Jev picks the ACR scenario in 0.5s and selects the most appropriate imaging studies. Link

One card in the feed, every sixteen, on every page of it. $50 a week, cancel any week.
Udit Akhouri announced Mores Research, a lab using behavioral classifiers such as TypeSafe AI's Jev to conduct long-horizon real-time behavioral intent mapping for pediatric mental health.

OpenMed tested on four fictional medical notes: Jev scored 16/16, Laya 13/16; on medication-conflict questions 4/4 vs 2/4. The author notes this is a useful diagnostic, not a clinical accuracy estimate.

Ali Madad presented givecareapp's InvisibleBench, rebuilt with TypeSafe AI's Jev, at a caregiving research conference in Utah.

Jev model demonstrates reading CT scans, potentially for medical imaging analysis.

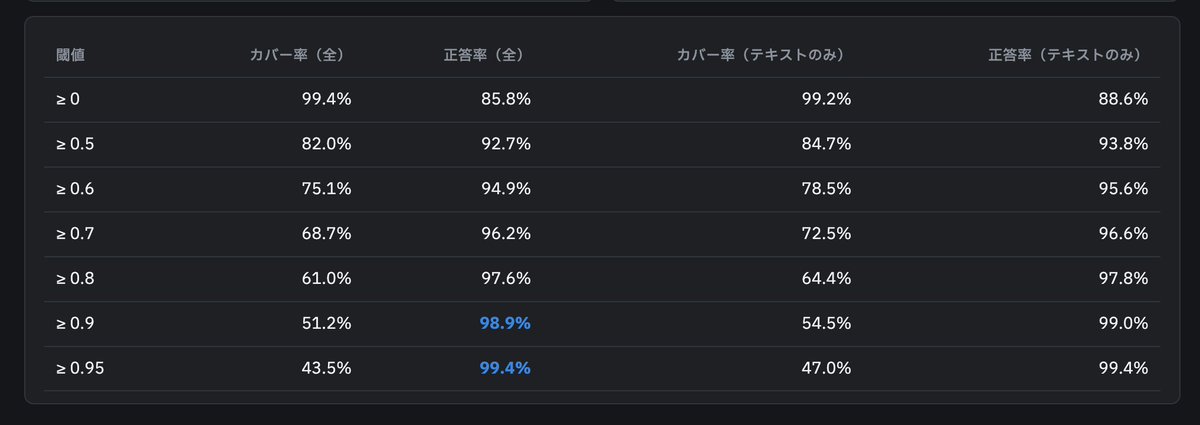
A user tested Jev on the medical QA benchmark igakuQA: 2,000 questions solved in about 80 seconds for $0.04; text-only accuracy was 88.6%, comparable to GPT-4o; using confidence cutoffs further improved accuracy.
Inspired by Jev and the open-source community, MedJev turns free-text clinical notes into structured fields and runs on consumer GPUs.

The post explains that Jev is not another chatbot but is built to choose, score and route, while an LLM drafts, summarizes and converses. In a clinic, the LLM handles language, Jev checks or routes the output, and staff stays in control.
