Jev versus text-generating models
Jev does not generate free-form text. A side-by-side video compares parallel decision-making with token-by-token text generation.
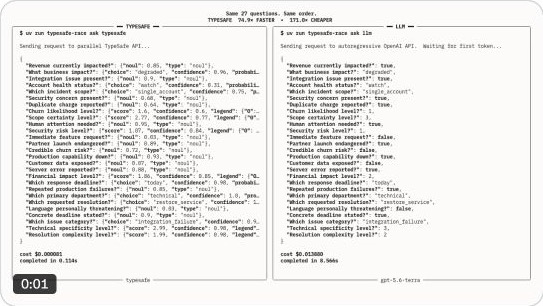
Run the Jev decision model locally via Ollama 0.35. Feed a text and get suggestions on which team to assign, whether to refund, and urgency. Each output has probabilities; the score (e.g., 0.815) is a probability-weighted average, so it should not be confused with confidence.
Ollama 0.35 รันโมเดลตัดสินใจแบบ Jev บนเครื่องเราได้แล้ว ป้อนข้อความเดียว ได้คำตอบทั้งว่าส่งทีมไหน ขอเงินคืนไหม และด่วนแค่ไหน ทุกคำตอบมีความน่าจะเป็นแนบมา แต่ตัวเลขพวกนี้อ่านผิดง่าย score 0.815 คือระดับเฉลี่ยที่ถ่วงด้วยความน่าจะเป็น ส่วน confidence

Jev does not generate free-form text. A side-by-side video compares parallel decision-making with token-by-token text generation.
The launch thread explains code-and-AI workflow evaluations, the input price announced at launch, and free output tokens.


This model is built for decision-making rather than text generation, outputting probabilities for each option in parallel instead of token-by-token responses. The author shares a simplified comparison of normal LLMs versus this Jev model.
